警告
基礎模型微調已達生命週期終止(EoL),且已不再受支援。 該 databricks_genai 套件及 Foundation Model 微調介面已不再提供。
Databricks 推薦 AI Runtime 來訓練與微調基礎模型,提供無伺服器、GPU 支援的環境。
重要
這項功能在下列區域開放公開預覽:centralus、eastus、eastus2、northcentralus 和 westus。
本文說明了基礎模型微調(現為 Databricks 模型訓練的一部分)所接受的訓練與評估資料檔案格式。
筆記本:訓練運行的資料驗證
下列筆記本示範如何驗證資料。 它的設計目的是在訓練開始之前能夠獨立運行。 它驗證您的資料是否符合基礎模型微調的正確格式,並包含程式碼,透過將原始數據集標記化,協助您在訓練運行期間預估成本。
驗證訓練回合筆記本的資料
整理數據以完成聊天對話生成
對於聊天完成工作,聊天格式化的數據必須位於 .jsonl 檔案中,其中每一行都是代表單一聊天會話的個別 JSON 物件。 每個聊天工作階段都以具有單一鍵的 JSON 物件 (messages) 代表,並對應到訊息物件陣列。 若要訓練聊天數據,請在 task_type = 'CHAT_COMPLETION'時提供 。
聊天格式中的訊息會根據模型的 聊天範本自動格式化,因此不需要新增特殊的聊天令牌來手動發出聊天回合開頭或結尾的訊號。 使用自訂聊天模板的模型範例是 Meta Llama 3.1 8B 指示。
陣列中的每個訊息物件都代表交談中的單一訊息,並具有下列結構:
-
role:代表訊息作者的字串。 可能的值是system、user、assistant。 如果角色是system,它必須是訊息列表中的第一個聊天。 至少必須有一條包含角色assistant的訊息,且(可選的)系統提示之後的任何訊息都必須在使用者和助理兩者之間交替角色。 兩則相鄰訊息不能有相同角色。messages陣列中的最後一則訊息必須具有角色assistant。 -
content:包含訊息文字的字串。
注意
Mistral 模型在其資料格式中不接受角色 system。
以下是聊天格式資料範例:
{
  "messages": [
    { "role": "system", "content": "A conversation between a user and a helpful assistant." },
    { "role": "user", "content": "Hi there. What's the capital of the moon?" },
    {
      "role": "assistant",
      "content": "This question doesn't make sense as nobody currently lives on the moon, meaning it would have no government or political institutions. Furthermore, international treaties prohibit any nation from asserting sovereignty over the moon and other celestial bodies."
    }
  ]
}
準備持續預先訓練的資料
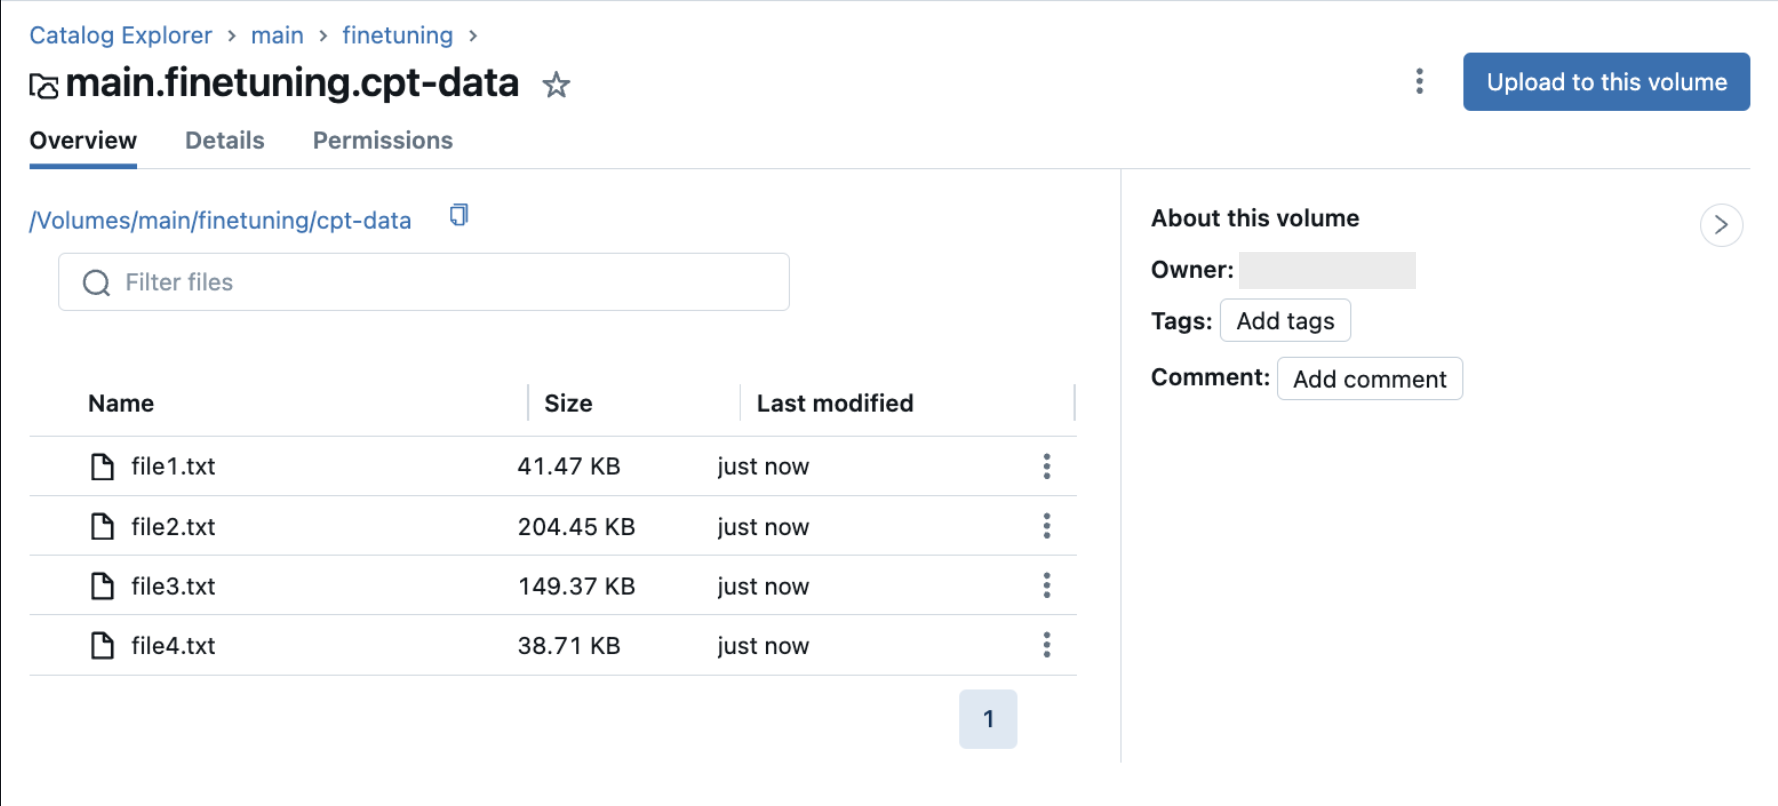
針對持續預先訓練工作,訓練資料是非結構化文字資料。 訓練數據必須位於包含 .txt 檔案的 Unity Catalog 磁碟區中。 每個 .txt 檔案都會視為單一範例。 如果您的 .txt 檔案位於 Unity Catalog 磁碟區資料夾中,也會取得這些檔案以供訓練數據使用。 會忽略磁碟區中的任何非 txt 檔案。 請參閱 在 Unity Catalog 磁碟區中處理檔案。
下圖顯示 Unity 目錄磁碟區中 .txt 檔案的範例。 若要在持續預訓練運行設定中使用這些資料,請設定 train_data_path = "dbfs:/Volumes/main/finetuning/cpt-data" 並設定 task_type = 'CONTINUED_PRETRAIN'。
自行格式化數據
基礎模型微調可讓您自行進行數據格式設定。 定型及提供模型時,必須套用任何數據格式設定。 若要使用格式化的數據來訓練您的模型,請在建立訓練運行時設定 task_type = 'INSTRUCTION_FINETUNE'。
訓練和評估資料必須符合下列其中一個格式:
提示和回覆組。
{ "prompt": "your-custom-prompt", "response": "your-custom-response" }提示與完成對。
{ "prompt": "your-custom-prompt", "completion": "your-custom-response" }
重要
提示-回應和提示完成 不會被範本化,因此任何特定於模型的範本化,例如 Mistral 的 指示格式設定,都必須作為前置處理步驟執行。
支援的數據格式
以下是支援的資料格式:
有
.jsonl檔案的 Unity Catalog 磁碟區。 訓練資料必須是 JSONL 格式,其中每一行都是有效的 JSON 物件。 下列範例顯示提示和回應組範例:{ "prompt": "What is Databricks?", "response": "Databricks is a cloud-based data engineering platform that provides a fast, easy, and collaborative way to process large-scale data." }符合上述其中一個可接受架構的 Delta 資料表。 針對 Delta 資料表,您必須提供用於資料處理的
data_prep_cluster_id參數。 請參閱設定訓練回合。公開 Hugging Face 資料集。
如果您使用公用 Hugging Face 資料集作為訓練資料,請使用分割指定完整路徑,例如
mosaicml/instruct-v3/train and mosaicml/instruct-v3/test。 這是針對具有不同分割結構的資料集而設。 不支援來自 Hugging Face 的巢狀資料集。如需更廣泛的範例,請參閱 Hugging Face 上的
mosaicml/dolly_hhrlhf資料集。下列資料列範例來自
mosaicml/dolly_hhrlhf資料集。{"prompt": "Below is an instruction that describes a task. Write a response that appropriately completes the request. ### Instruction: what is Databricks? ### Response: ","response": "Databricks is a cloud-based data engineering platform that provides a fast, easy, and collaborative way to process large-scale data."} {"prompt": "Below is an instruction that describes a task. Write a response that appropriately completes the request. ### Instruction: Van Halen famously banned what color M&Ms in their rider? ### Response: ","response": "Brown."}